Architecture Overview
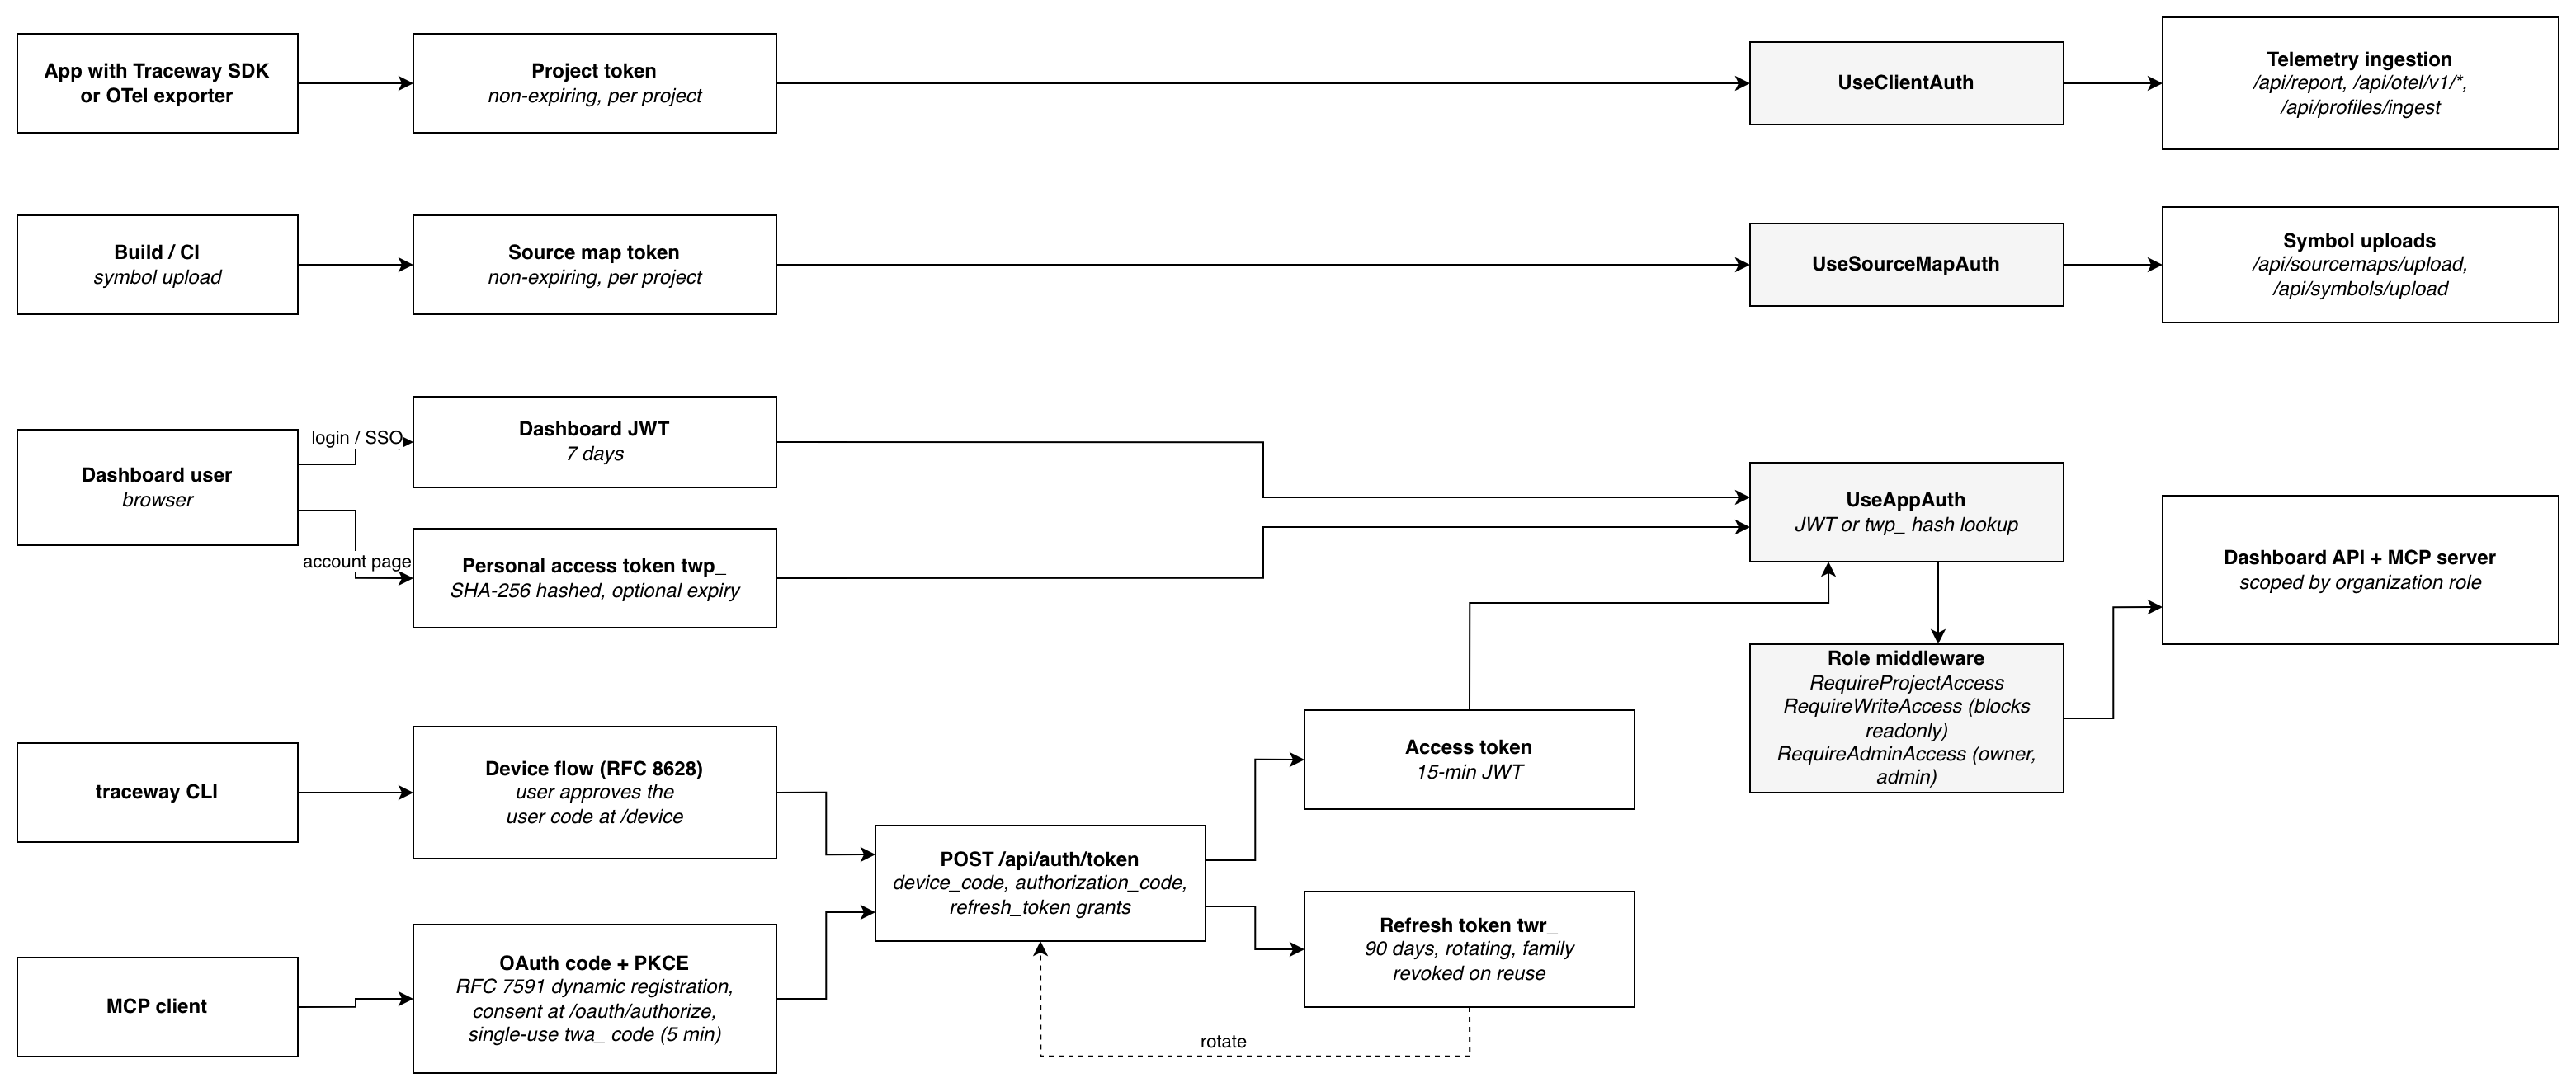
TracePath's mental model is small. There's one underlying primitive, spans, and a handful of materialized views over those spans that make the dashboard fast.
The primitive: spans
Every piece of trace data TracePath ingests is an OpenTelemetry span. Spans carry a name, a kind, a duration, attributes, events (exceptions live here), and parent/trace ids. The shape is OTel-native: TracePath speaks OTLP directly and doesn't impose its own trace model on top.
The materialized views
On ingestion, TracePath classifies each span and writes a row into a dedicated table when the kind or attributes match a rule. These tables are the top-level dashboard concepts:
- Endpoints: inbound HTTP entry points (
GET /api/users/:id). - Tasks: queue consumers, scheduled commands, anything that runs as a "thing that completes".
- AI Traces: any span carrying
gen_ai.*attributes, root or child. - Issues: exception events lifted off whichever entity owned the span.
Each table is indexed and shaped for one job: answering "what's slow?", "what's expensive?", "what's failing?" without scanning the full span store. They're projections, not parallel universes: the underlying span data is the source of truth.
Trace classification rules and the views → · Issues → · AI Tracing →
Root and non-root entities
Endpoints, Tasks, and AI Traces all carry an is_root flag. A row is non-root when the span that produced it was triggered by another trace: a queue worker started by an HTTP request, an LLM call made inside that same handler, a downstream service hop. Non-root rows link back to the originating trace via the auto-derived distributed_trace_id, so the distributed-trace view shows the full picture across all the entities that share one OTel trace id.
Enrichments
- Attributes: key-value metadata on spans and the entities derived from them. Flow from global → per-request scope. Details →
- Sessions: user-session grouping for browser/mobile clients, separate from traces. Details →
- Metrics: time-series measurements, ingested via OTLP metrics. Independent of the trace pipeline. Details →
- Logs: OTLP logs ingestion, joinable to traces by trace id. Details →
See Data Flow for how these connect during request processing, task execution, and metrics collection, and Project Structure for how to split an application across TracePath projects before you instrument it.
Above a single project
Everything above is scoped to one project. The Organization Overview sits above them all: every server reporting into the organization, every recently active issue, every monitor, and every open on-call page, each one a sidebar click apart. It is how a fleet of servers or a Kubernetes cluster is read at a glance before you drill into the project that owns the problem.
Authentication
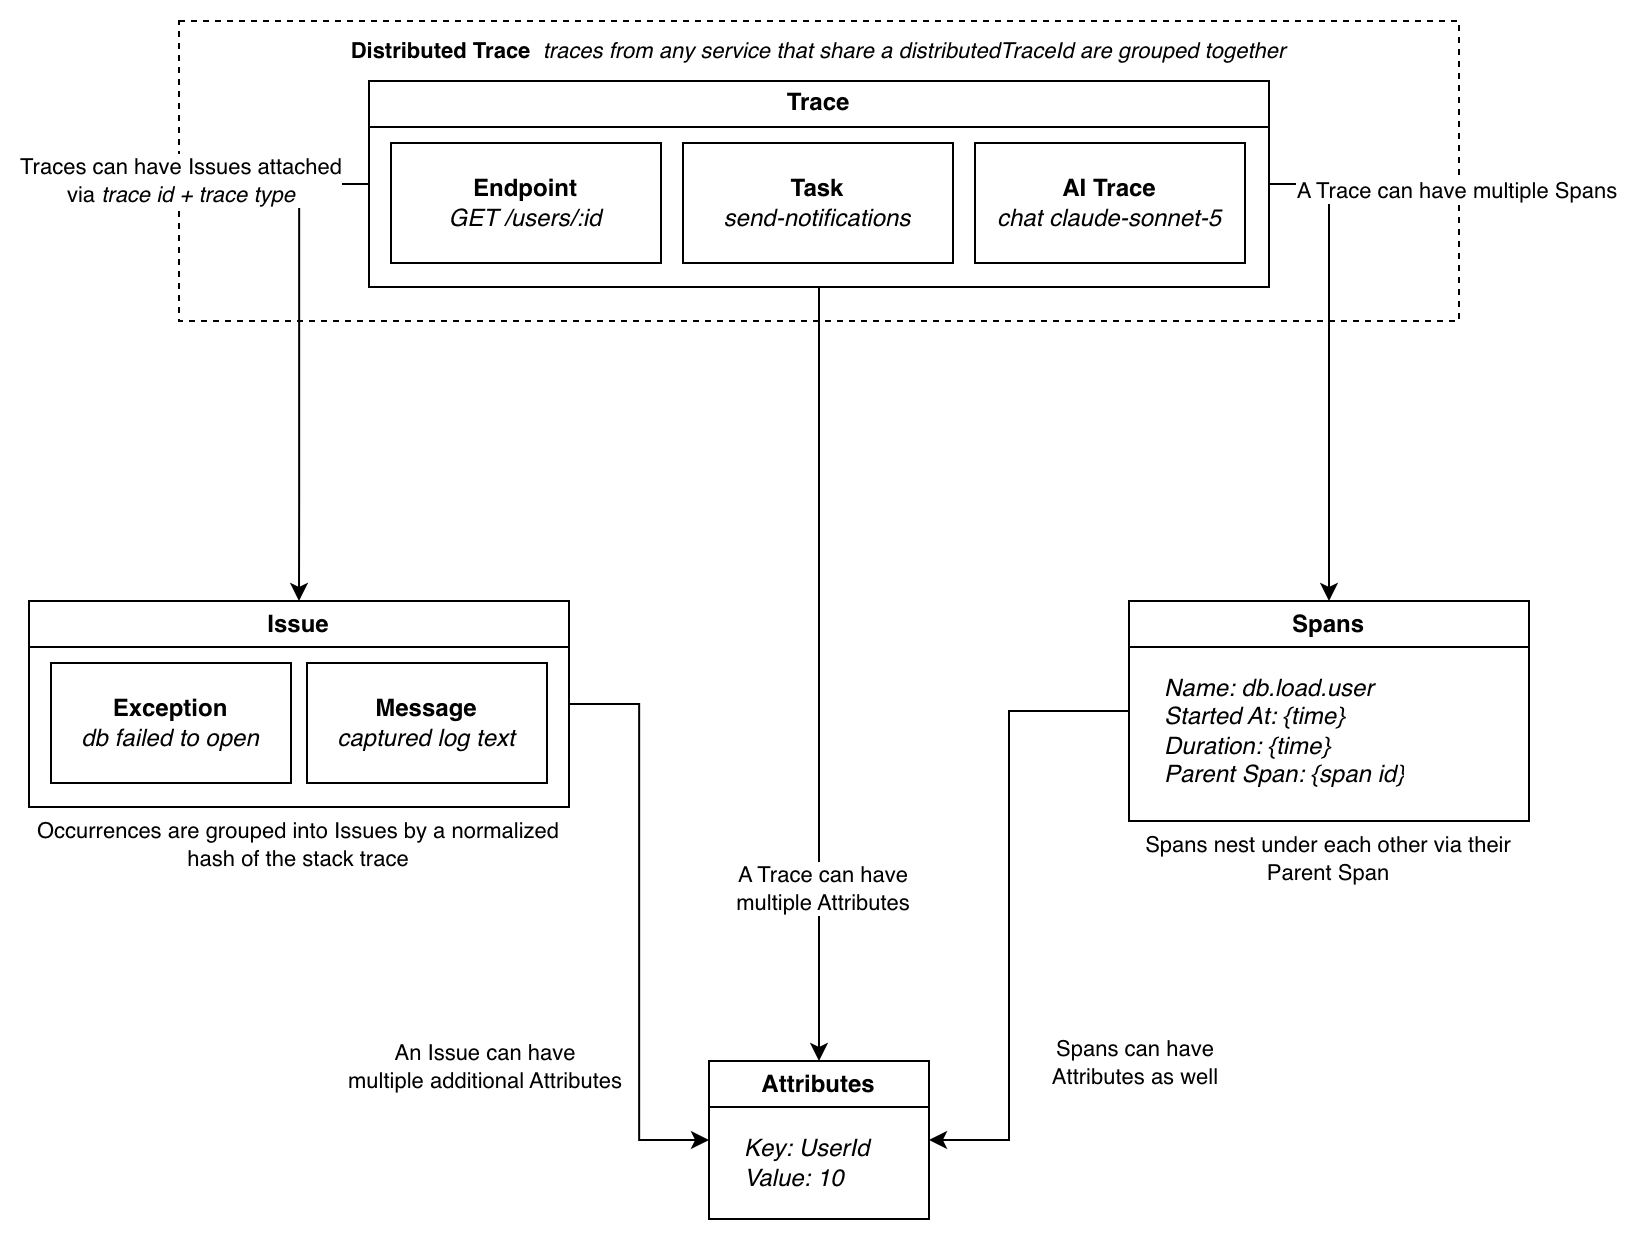
Every way in has its own credential, and they never substitute for one another:
| Credential | Used by | Sent as |
|---|---|---|
| Project token | OTLP exporters and collectors writing telemetry | Authorization: Bearer <project token> to ingest.tracepath.dev |
| Source map token | CI, uploading source maps | Authorization: Bearer <upload token> to /api/sourcemaps/upload |
| Session token | The dashboard, after you sign in | Held by the browser |
| Personal access token | Scripts and CI reading the management API | Authorization: Bearer tpp_… to app.tracepath.dev |
| OAuth access token | MCP clients, via authorization code + PKCE | Negotiated by the client |
An authenticated user is then scoped by their organization role and any per-project override; see Project Structure.